Package website | GitHub | Issues | Chinese guide
fastphylosig calculates phylogenetic signal for
continuous, binary, and categorical traits. Most analyses need one
function: fast_signal(). The method-specific functions
remain available when you want to inspect and control each step.
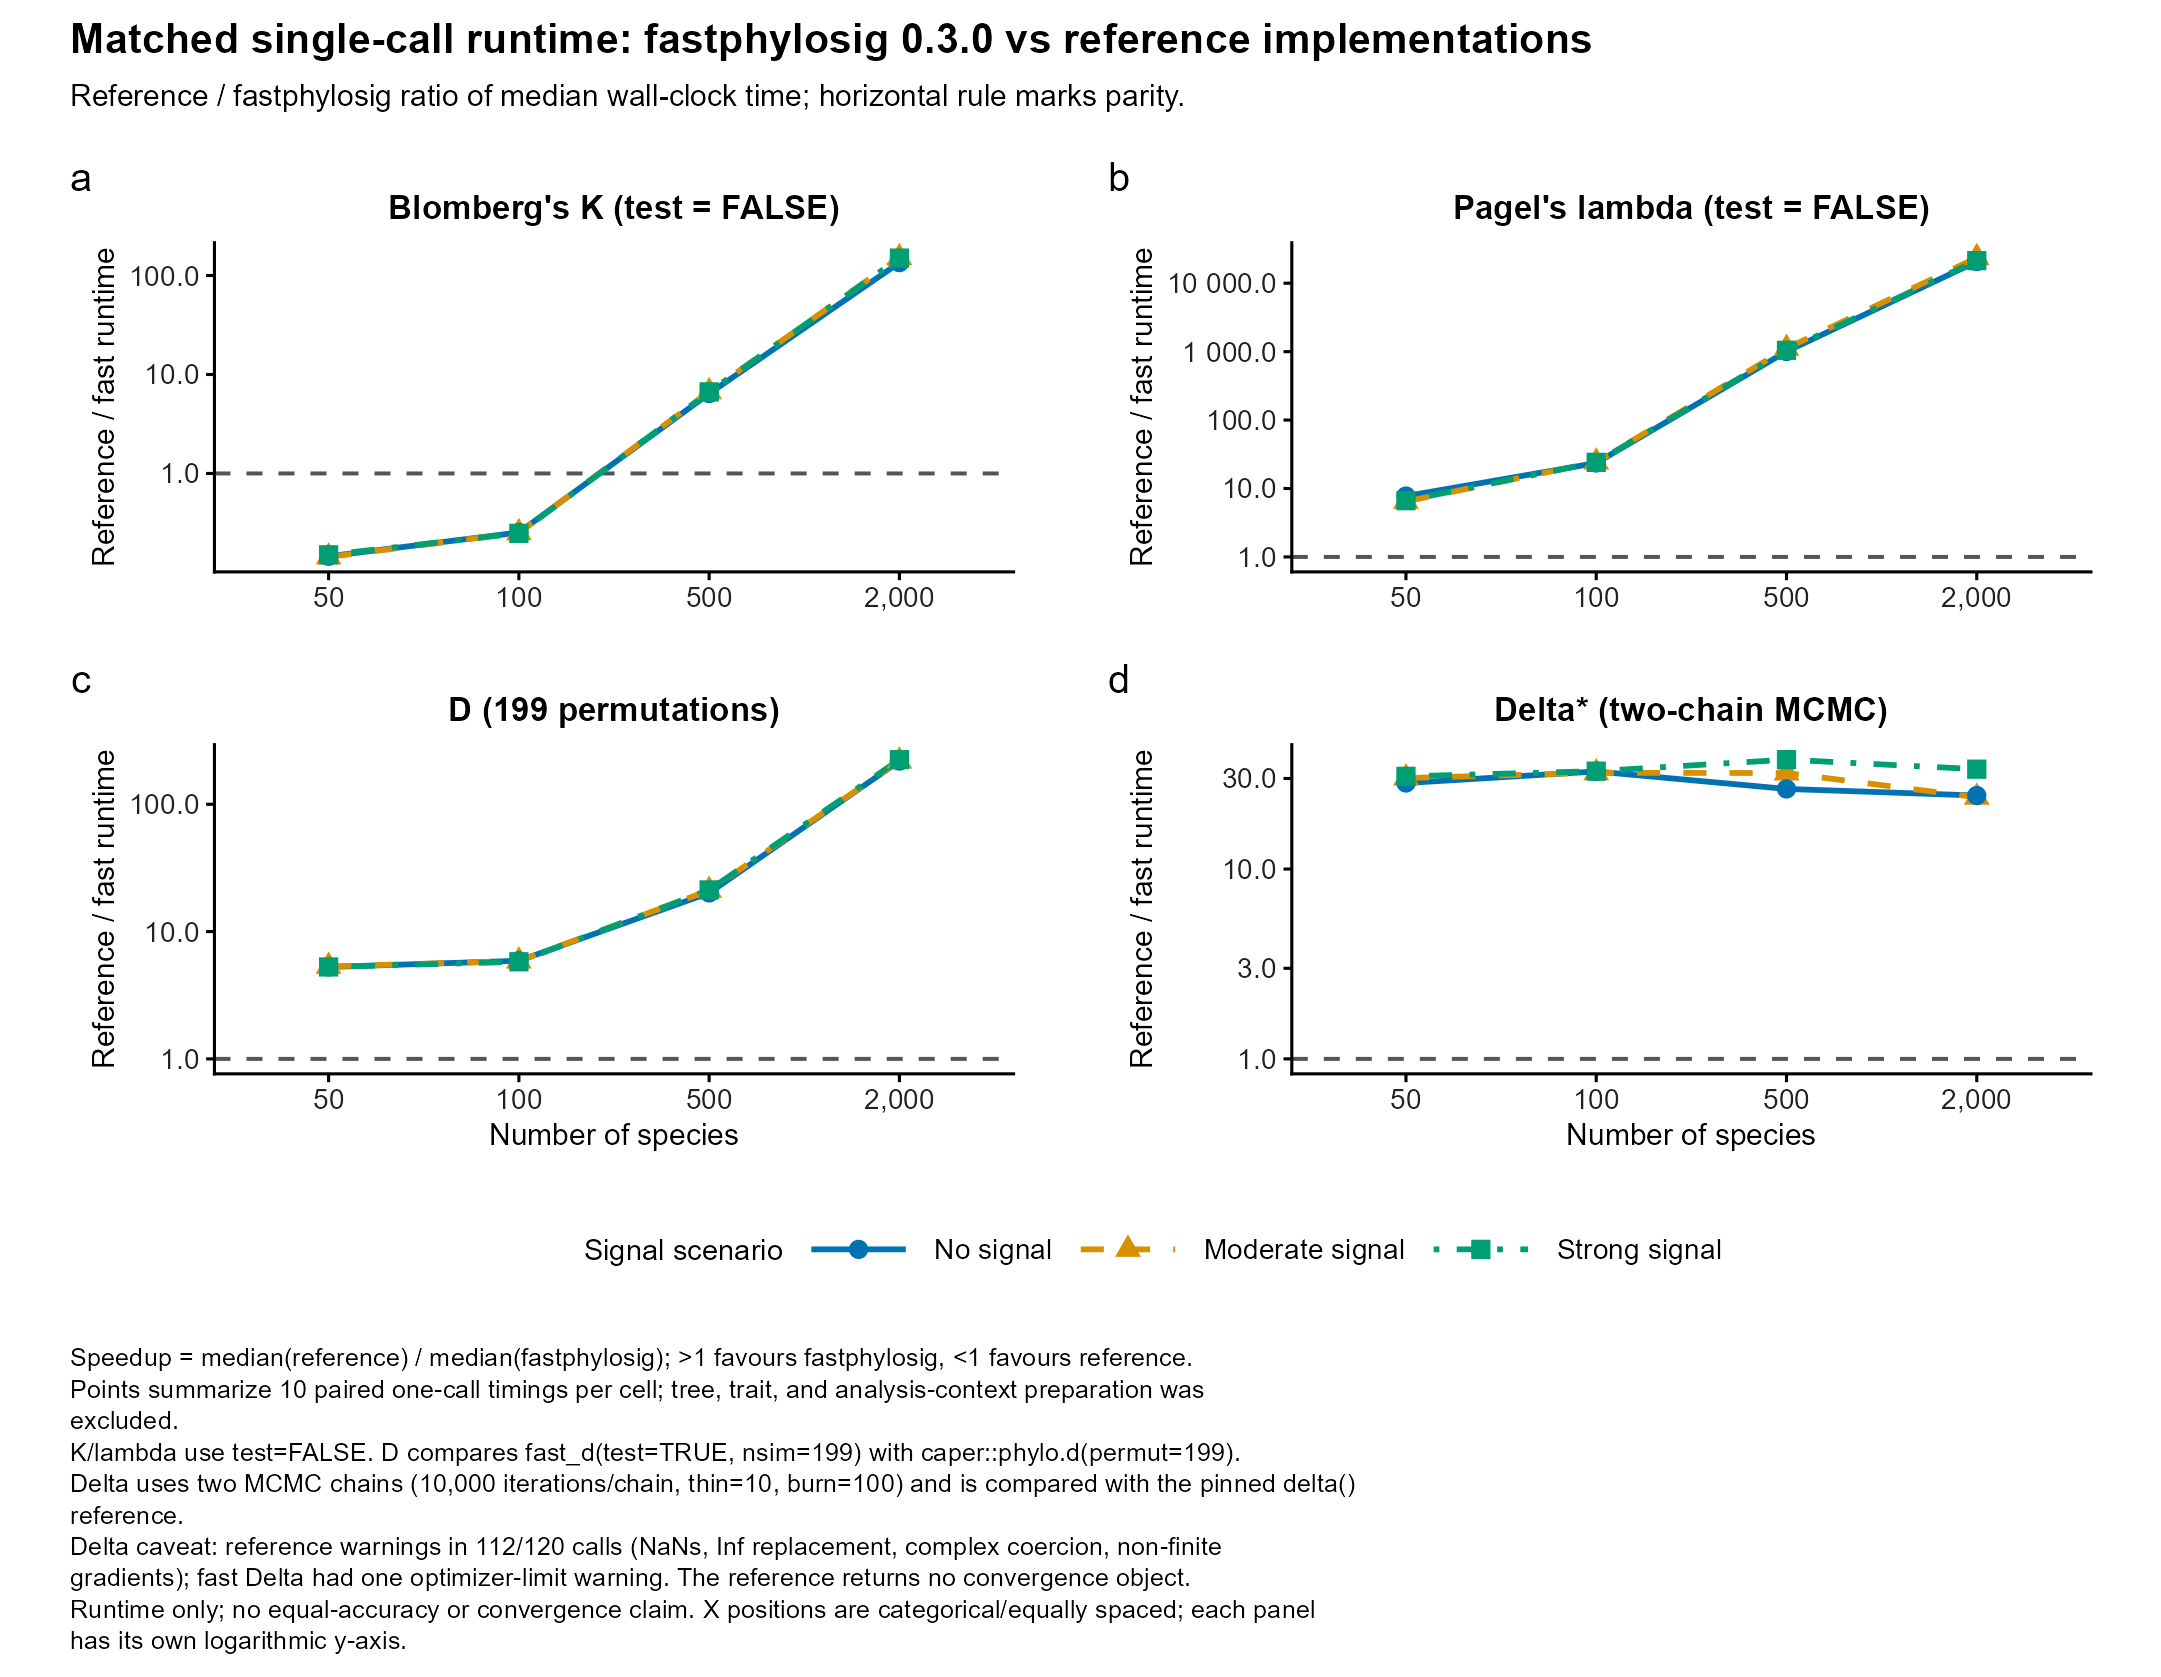
On 2,000-species trees, observed reference/fastphylosig median runtime ratios were 135–151 for K, 20,697–23,591 for lambda, and 218–224 for D across three simulated signal scenarios. Delta call-time ratios were 23.9–33.6, subject to the diagnostic caveat below. Each cell has 10 matched pairs; tree/data preparation is excluded. The dashed line is equal runtime; small-tree K is slower than phytools at 50 and 100 species, and those results remain visible.
References are phytools 2.5.2 (K/lambda), caper (D) and a pinned
Borges Delta implementation. K/lambda use test = FALSE; D
includes 199 randomizations; Delta uses two 10,000-iteration MCMC chains
without permutation testing. Delta caveat: 112/120
reference calls produced numerical warnings and did not expose final
convergence information; one fast call reached an optimization iteration
limit. Delta ratios describe observed returned-call times, not
demonstrated equal-accuracy or converged-fit speedups. These Windows/R
4.6.1 timings are workload-specific, not universal guarantees. See all
data, settings and diagnostic details.
The local 0.3.1 patch contains five correctness fixes; it has not been published. Install the supplied source archive with an existing C++ toolchain:
install.packages("fastphylosig_0.3.1.tar.gz", repos = NULL, type = "source")
library(fastphylosig)
For the previously published GitHub release:
install.packages("remotes")
remotes::install_github("yinwen-ecology/fastphylosig@v0.3.0")
library(fastphylosig)
Source installation requires a C++ toolchain. OpenMP is optional.
Once you have a phylo tree and named trait data, choose
a method and run:
set.seed(1)
tree <- ape::rtree(30)
trait <- stats::setNames(stats::rnorm(30), tree$tip.label)

fit <- fast_signal(
  tree, data = trait, method = "K", progress = FALSE
)
summary(fit)
That is enough for a standard analysis. fast_signal()
checks the tree, matches species, handles missing values trait by trait,
and runs the selected calculation.
Choose method from the question and trait type:
| Target | method |
Input | Returns |
|---|---|---|---|
| Blomberg’s K | "K" |
continuous | K estimate; optional permutation test |
| Pagel’s lambda | "lambda" |
continuous | lambda likelihood and LR test |
| Fritz–Purvis D | "D" |
binary | random and Brownian null comparisons |
| Delta | "Delta" |
categorical | Delta estimate, MCMC diagnostics, optional permutation test |
The method is always explicit; it is not guessed from trait values.
Use print(fit), summary(fit),
as.data.frame(fit), or plot_signal(fit) to
inspect the result. Unknown or method-inapplicable arguments produce an
error.
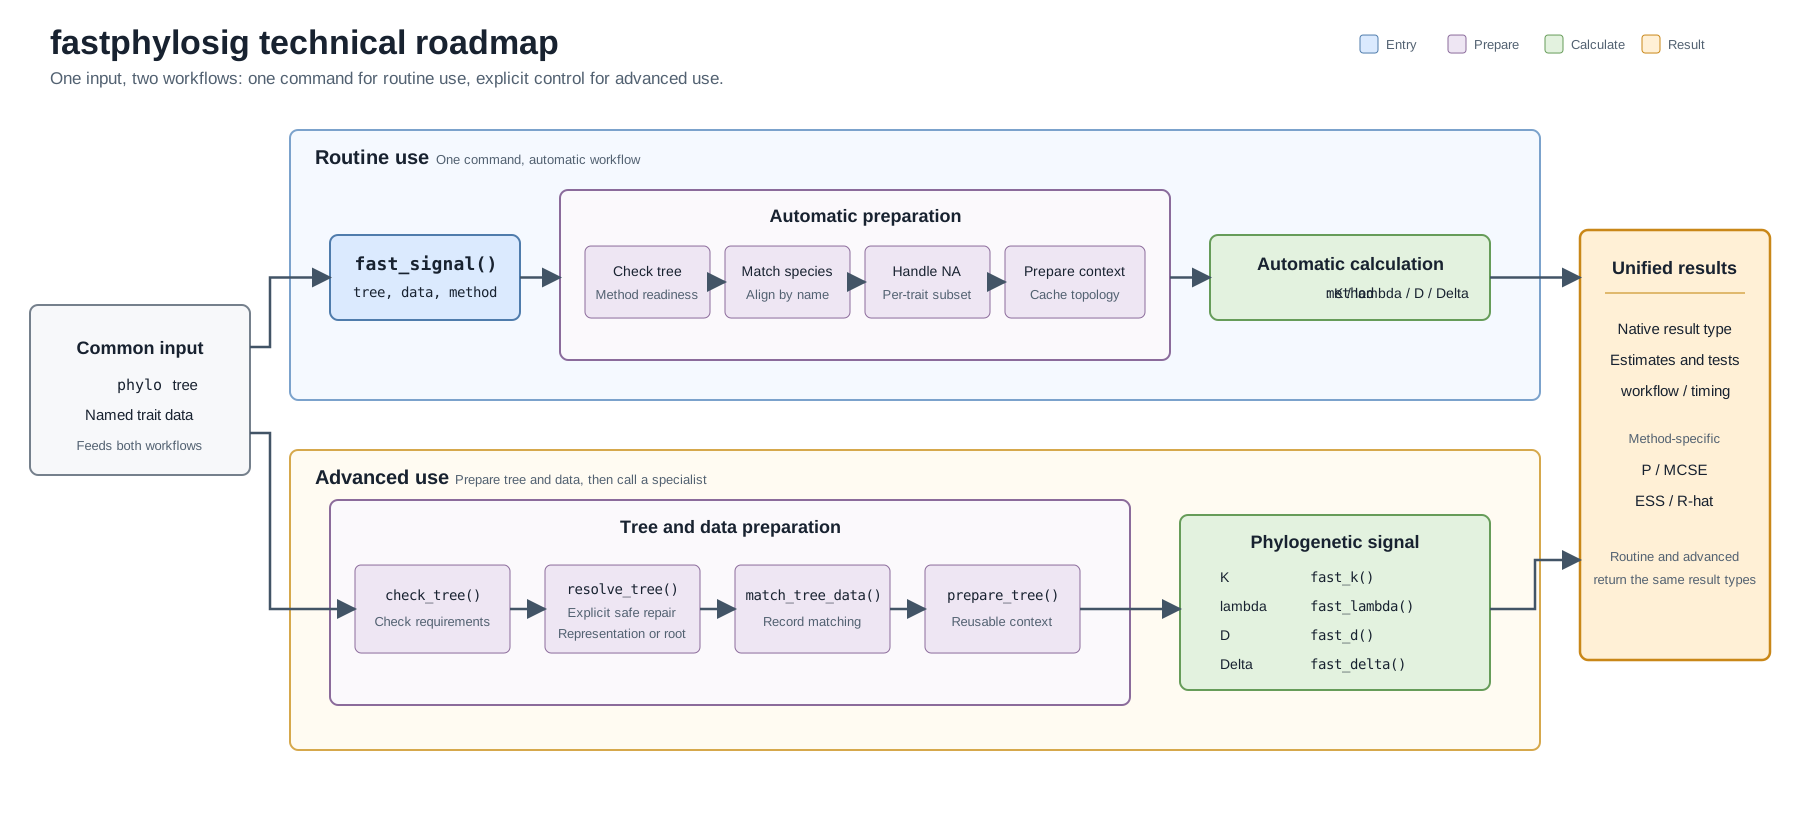
The tree and trait data feed either workflow. The general workflow performs the preparation boxes automatically. The advanced workflow exposes the same preparation order before a method-specific calculation. The editable draw.io source and Mermaid source are included for website use.
Use the explicit path when you need an auditable tree/data record or controls that belong to one method:
checked <- check_tree(tree, signal = "K")
checked

# Safe representation changes only; an explicit outgroup is required if the
# selected method needs a root and the tree is unrooted.
tree_ready <- resolve_tree(tree, signal = "K")
matched <- match_tree_data(tree_ready, data = trait)
ctx <- prepare_tree(matched$tree)
After preparation, call the method-specific function directly:
| Function | Trait | Statistical target |
|---|---|---|
fast_k() |
continuous | Blomberg’s K and permutation test |
fast_lambda() |
continuous | Pagel’s lambda likelihood and LR test |
fast_d() |
binary | Fritz and Purvis D with random and Brownian nulls |
fast_delta() |
categorical | Delta, MCMC diagnostics, and permutation test |
k_fit <- fast_k(ctx, x = matched$data, test = TRUE, nsim = 999,
                return_sim = TRUE, progress = FALSE)
lambda_fit <- fast_lambda(ctx, trait, test = TRUE,
                          lambda_profile = TRUE, progress = FALSE)
binary <- stats::setNames(as.integer(trait > stats::median(trait)),
                          tree$tip.label)
d_fit <- fast_d(ctx, binary, test = TRUE, nsim = 99,
                return_sim = TRUE, keep_null = TRUE, progress = FALSE)
categorical <- stats::setNames(rep(c("a", "b", "c"), length.out = 30),
                               tree$tip.label)
delta_fit <- fast_delta(ctx, categorical, test = TRUE,
                        mcmc_sim = 10000, thin = 10, burn = 100,
                        return_sim = TRUE, progress = FALSE)
The method-specific controls are deliberately separate: K uses
permutations and simulation_chunk; lambda uses
lambda_profile; D uses separate random and Brownian state
controls plus keep_null; Delta uses MCMC and permutation
controls. fast_ace() separately exposes the ancestral-state
reconstruction used by Delta. The result classes and legacy fields
remain stable.
Prepare a tree once when it will be used repeatedly:
ctx <- prepare_tree(tree)
X <- cbind(trait_1 = trait, trait_2 = trait + stats::rnorm(length(trait)))
fits <- fast_signal(ctx, data = X, method = "K", verbose = FALSE)
cache_info(ctx)
Preparation compiles topology and traversal data. Dense covariance,
Cholesky, and spectral payloads are not created by the production K,
lambda, D, or Delta paths. A prepared context is a snapshot: later
changes to the original phylo object do not update it. On
every external reuse, the V2 context schema and an exact protected
snapshot check the cached tree’s tip labels, edge matrix, branch
lengths, and Nnode value before any cache or numerical
kernel is used. Changes to those fields are rejected.
node.label and other non-computational attributes are
outside this integrity contract; node.label may be
reordered when internal nodes are renumbered. V2 contexts can be saved
with saveRDS() and reused after readRDS();
older or unrecognized context schemas must be rebuilt with
prepare_tree().
check_tree() is read only. resolve_tree()
may reorder edges and renumber internal nodes on a copy when this
changes representation only. V2 keeps tip IDs and tip.label
unchanged, assigns the root to n_tip + 1, orders child
subtrees by the exact UTF-8 byte order of their minimum descendant tip,
and numbers remaining internal nodes in canonical preorder. Edges are
emitted in canonical postorder while each branch length stays associated
with its biological child edge. The canonical computational
representation, fingerprint, and estimator outputs are invariant to
valid internal-node renumbering and edge-row order in the tested
fixtures and locales. These functions do not guess a biological root,
select an outgroup, invent or jitter branch lengths, resolve biological
polytomies, ultrametricize a tree, or silently delete tips.
match_phylo_data() remains a deprecated alias for
match_tree_data().
Method boundaries are intentional:
fast_ace() require a conventionally rooted,
fully binary tree with finite, strictly positive branches.se != NULL) is not
implemented.Species identifiers should be unique vector names or
matrix/data-frame row names. Their input order need not match the tree:
matched data are reordered to tree-tip order. An unnamed input is
accepted only when its entries or rows already correspond to
tree$tip.label order. Missing values are then handled per
trait. Each unique retained-tip mask is validated and cached once.
Inputs are not modified. A wrong positional order without identifiers
cannot be detected automatically and can assign traits to the wrong
species.
K randomization supports explicit permutation matrices, bounded
chunks, and optional null retention. D reports separate P values and
Bernoulli Monte Carlo standard errors (MCSE_P_random and
MCSE_P_Brownian) for its random and Brownian nulls, using
the finite successful count for each null. These fields are
NA when test = FALSE. D retains both null
vectors only when both return_sim = TRUE and
keep_null = TRUE; their defaults are respectively
test and return_sim.
Lambda can retain an approximate likelihood profile. The nominal 95%
interval uses a regular grid and the cutoff
max(logL) - 0.5 * qchisq(0.95, df = 1); threshold crossings
are linearly interpolated. It is a grid/profile approximation, not an
exact confidence interval.
Delta defaults include test = FALSE,
nsim = 1000, return_sim = test,
mcmc_sim = 10000, thin = 10,
burn = 100, and model = "ARD"; therefore no
permutation P value or null vector is produced unless testing is
enabled. With test = TRUE, MCSE_P uses the
number of finite successful permutations, and
return_sim = TRUE retains the Delta null vector. Interpret
ESS, split R-hat, MCSE_Delta, and, when present,
MCSE_P together with the point estimate. Fewer than two
species shared globally by the tree and data is a call-level error.
After matching, a trait with fewer than two non-missing species receives
an explicit per-trait insufficient-data result; a completed trait with
2–19 retained species contributes to one batch warning. Non-finite
diagnostics, ESS below 20, or split R-hat above 1.1 also produce one
batch warning. Warnings never rerun or extend the chain
automatically.
Use set.seed() or controlled permutations for stochastic
comparisons. Record the package version, tree/data fingerprints,
simulation counts, threads, chunk sizes, and whether preparation time is
included.
For throughput:
prepare_tree() context.ncores for K randomization, binary-tree D, or
sufficiently large Delta permutation jobs; small parallel jobs may be
slower than serial work.progress = FALSE to suppress progress stages and
species-matching messages. Statistical warnings and errors are still
signalled. Results retain timing metadata.For stochastic parallel paths, replay requires the seed, explicit
simulation inputs (when supplied), and ncores to be held
fixed. In particular, changing Delta’s process count repartitions worker
RNG streams and is not guaranteed to reproduce null draws or derived
P/MCSE values draw for draw. Explicit permutation/state matrices isolate
the corresponding randomization step, but Delta’s MCMC fits remain
stochastic. Record the worker configuration with the result. Small jobs
may be faster in serial.
plot_signal(k_fit)
plot_signal(lambda_fit)
plot_signal(d_fit)
plot_signal(delta_fit)
Null-distribution plots require retained simulations. Use
return_sim = TRUE for K and Delta; D requires both
return_sim = TRUE and keep_null = TRUE.
plot_signal()
displays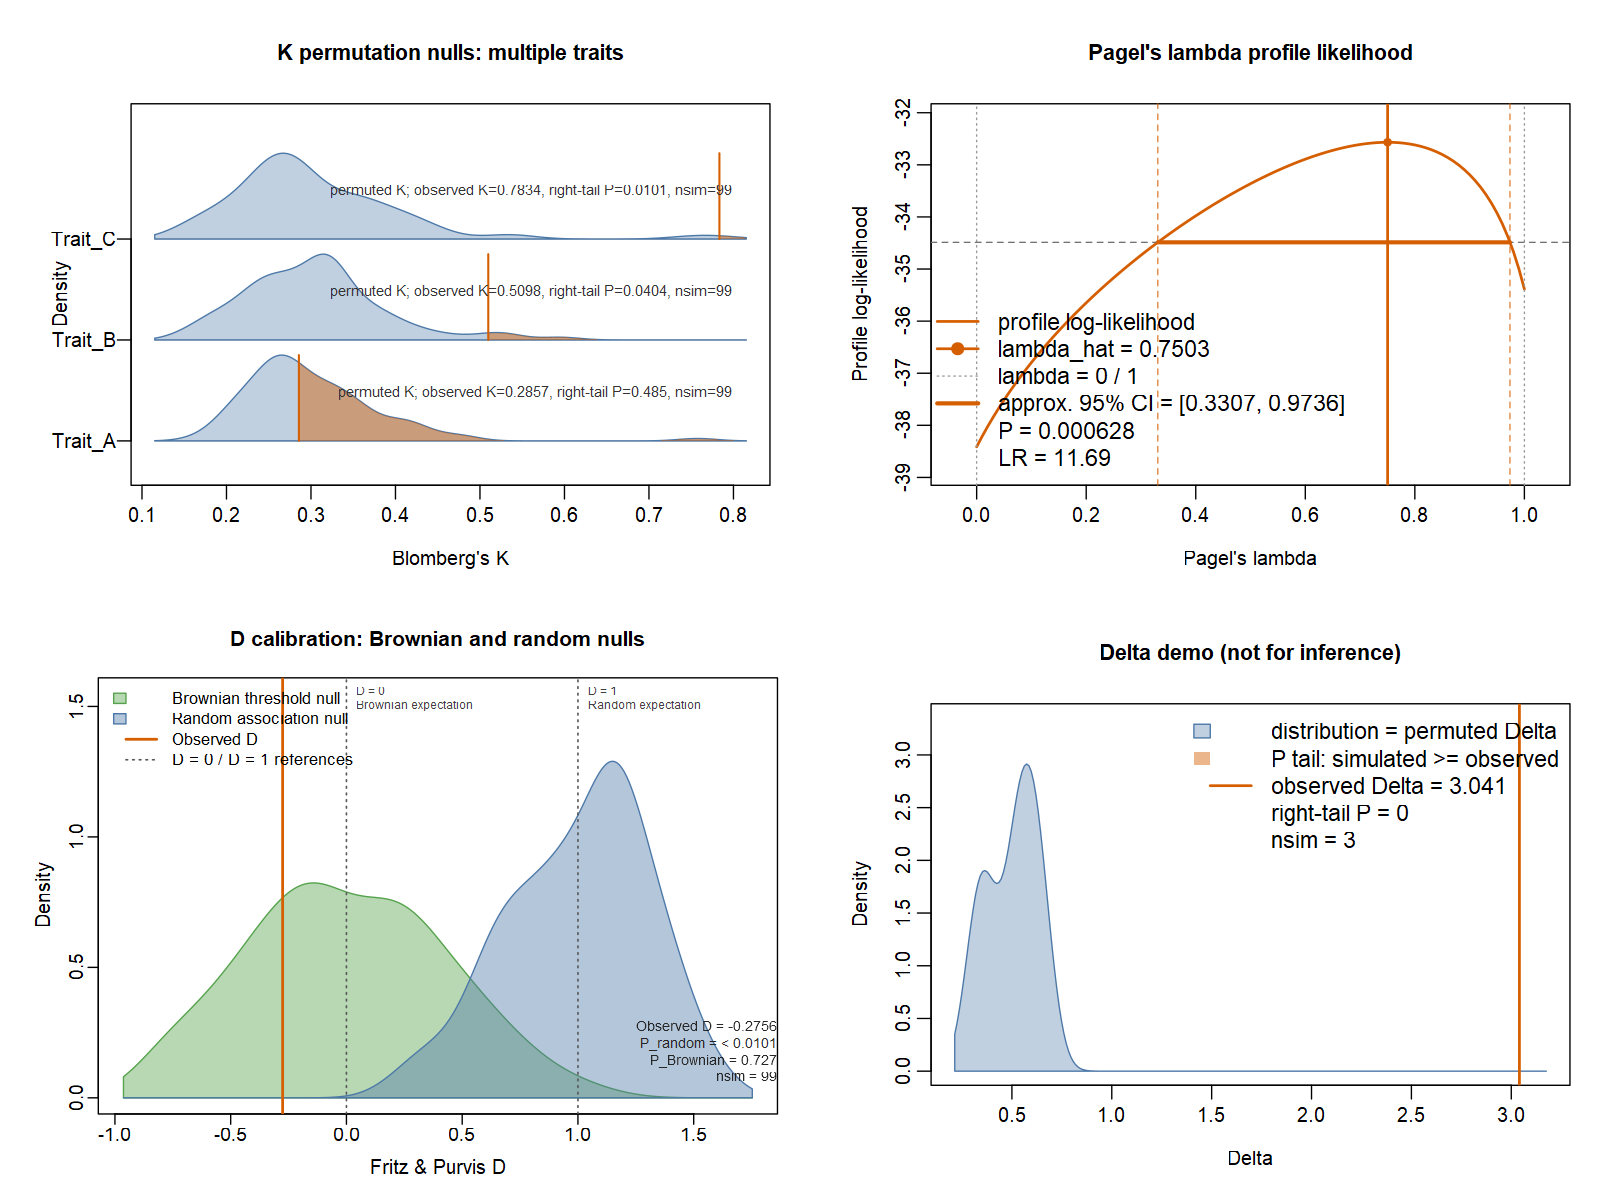
The examples show multi-trait K permutation ridges, a lambda
likelihood profile, D calibration against random and Brownian nulls, and
a categorical Delta permutation distribution. They are actual
plot_signal() outputs from version 0.3.0 on simulated
demonstration data, not empirical findings. See the gallery
and reproducible R code for single-trait K and separate D null
displays, seeds, simulation settings, and diagnostic caveats. The short
Delta example is for illustration, not scientific inference. These
native web previews retain some annotation/curve overlaps; they are not
collision-free manuscript figures.
The local 0.3.1 patch fixes D type-7 thresholds, numeric species identities, D plot null probabilities and tails, approximately ultrametric lambda boundaries, and long mask-cache identities. See patch notes. Its 50K regression covers preparation, subset caches, persistence, fallback grouping and K without permutations. It does not qualify all methods or simulation workloads at 50K. The historical figures and runtime evidence below remain evidence for 0.3.0; no new performance benchmark was run for 0.3.1.
The 0.3.0 release retains declared compatibility with R 4.1.0 and above. Its public API, estimator definitions, RNG stream, and thread policy are unchanged from 0.2.0. K values may differ at floating-point rounding scale; the Stage 5 numerical and release checks document the qualification boundary. Current performance evidence is from the production 0.3.0 implementation on Windows with R 4.6.1/Rtools 4.5, not from the Stage 3C prototype. Cross-platform, R-devel, and second-BLAS qualification remain outside this local validation scope.